Chung-Ming Chien (簡仲明)
Chicago, Illinois, United States
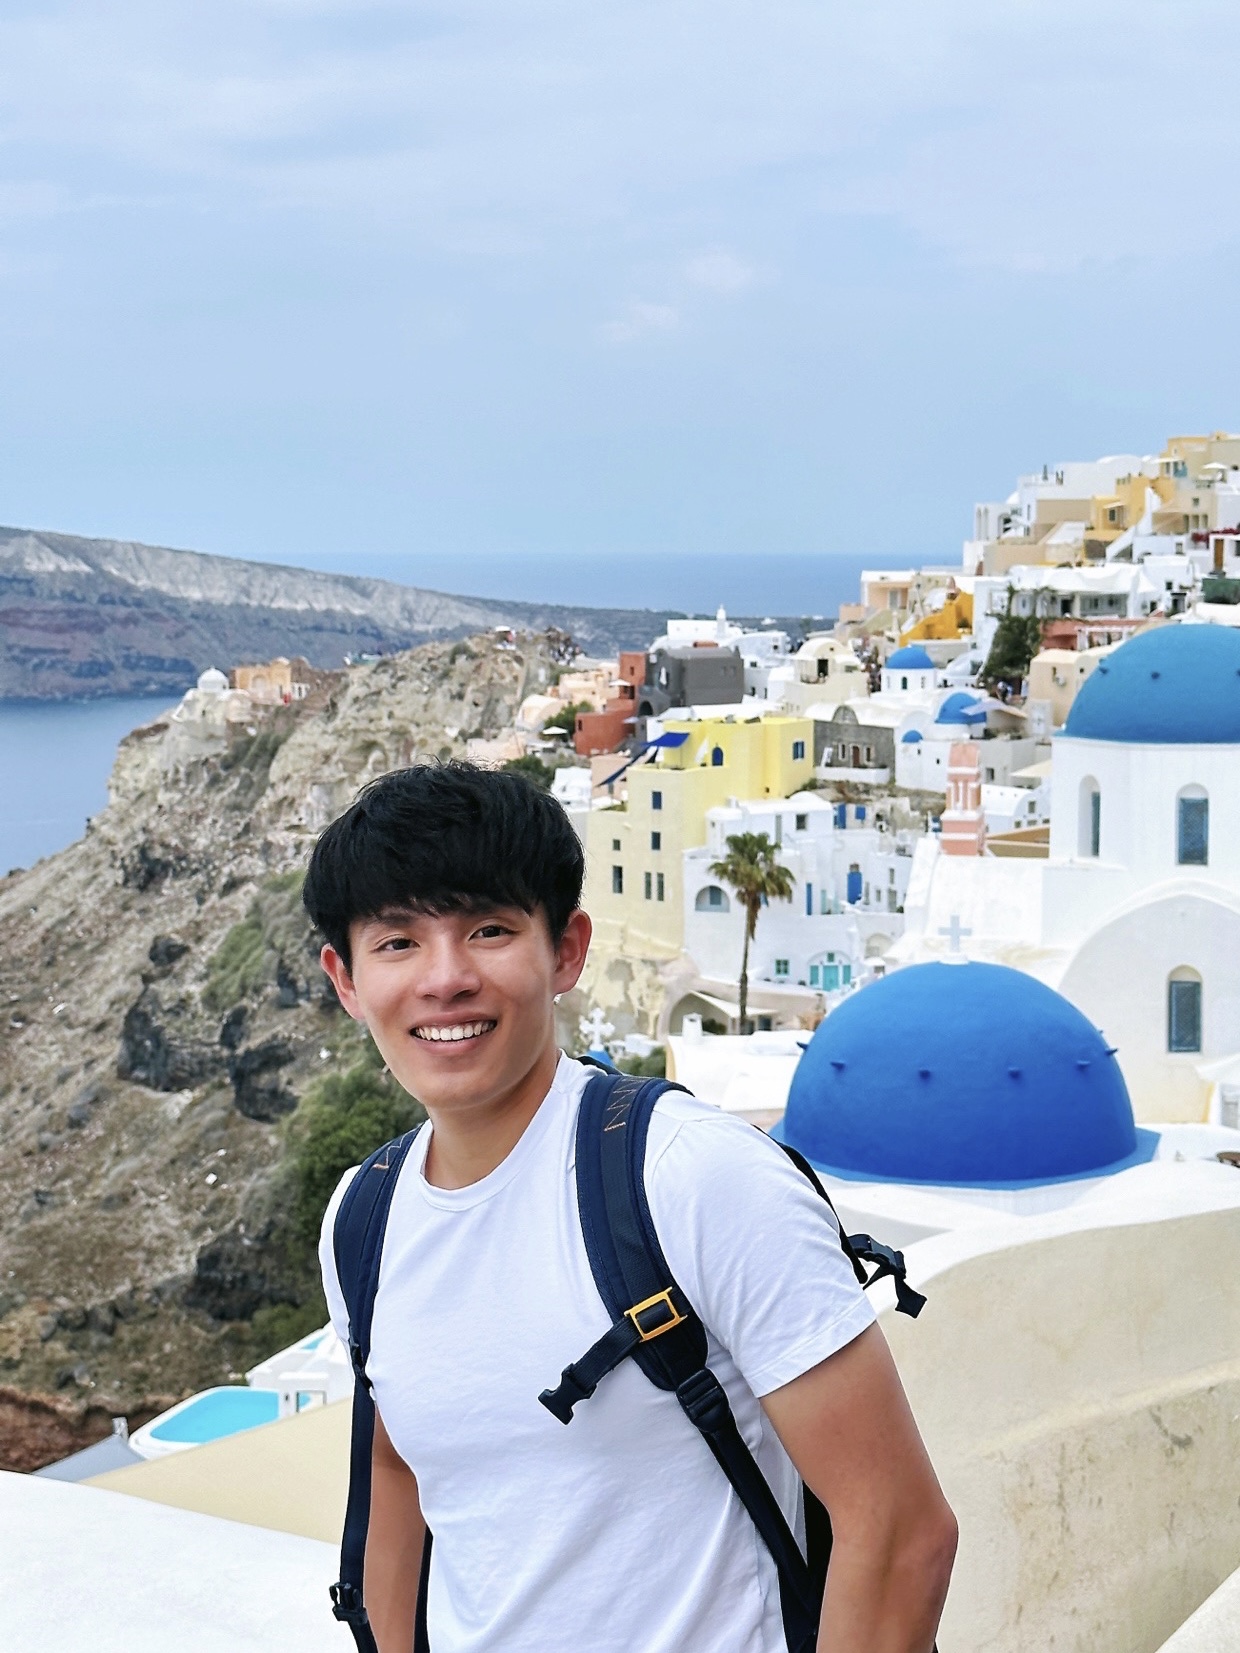
Santorini, Greece
May 30, 2023
I am a 5th-year Ph.D. student at Toyota Technological Institute at Chicago (TTIC), advised by Karen Livescu. My overarching goal is to create Trustworthy, User-Friendly, and Human-Like Voice AI. My current research focuses on two key directions:
- Balancing Intelligence with Interactivity in Voice AI
How can we make full-duplex voice models more intelligent without compromising real-time interactivity? How can we better preserve the knowledge acquired during large-scale text pre-training? How should a voice model decide what to delegate, to whom, and when—whether to a larger language model, a text-based reasoning system, or external tools? - Aligning Speech Language Models (SLMs) with Human Preference
How can we align SLMs with human preferences to improve content fidelity, natural turn-taking, and emotional responsiveness? How to enhance overall user experience?
Aside from these, my past research in Controllable Speech Generation, Efficient Fine-Tuning of SLMs, Flow-Matching & Diffusion Models, and Self-Supervised Speech Representations has provided a strong technical foundation for pursuing these goals.
Prior to joining TTIC, I completed my Master’s degree in Computer Science at National Taiwan University (NTU), where I had the fortune to work with Lin-shan Lee and Hung-yi Lee at the Speech Processing Lab. I also gained valuable practical experience through summer internships at Amazon Alexa TTS Research, FAIR (AI at Meta), NVIDIA NeMo Team, and Kyutai.


Beyond my academic and research pursuits, I am an avid sports enthusiast and amateur athlete. During my undergraduate studies, I captained the varsity baseball team at NTU. I maintain a broad interest in tennis, hiking, snowboarding, scuba diving, and badminton. I set a half marathon PB of 1:22:16 earlier in 2026 and am currently working toward my first BQ.
news
| Sep 27, 2026 | I completed my first half marathon in 82:16 🏃🏻➡️ |
|---|---|
| Sep 27, 2026 | I give a talk at the Interspeech 2026 tutorial On the Landscape of Spoken Language Models in Sydney  |
| Sep 24, 2026 | I give a talk at xAI on MoshiRAG |
| Jul 9, 2026 | I will present MoshiRAG at ICML 2026 in Seoul. Orchestrating intelligence with interactivity is the future of voice AI  |
| Apr 29, 2026 | MoshiRAG is released as the world’s first full-duplex speech language model with retrieval-augmented generation (RAG)! Check out the paper, code, and blog post. Excited to present it at ICML 2026! |
| Sep 5, 2025 | It was a true pleasure reconnecting with old friends and meeting new colleagues at the Workshop on Foundations of Speech and Audio Foundation Models in TTIC. It is my greatest hope that you found the event valuable and enjoyable. |
| Jul 17, 2025 | I will be co-hosting the Workshop on Foundations of Speech and Audio Foundation Models this September. Join us at TTIC to explore the newest advancements in Speech Language Models. |
| Apr 18, 2025 | This summer, I am heading to France to join Kyutai and work on moshi, the world’s first full-duplex speech assistant. This is a fresh trial, and I can’t wait to see what we achieve! Bonjour Paris  |
| Apr 11, 2025 | The long wait is over. Our review paper on SLMs, “On the landscape of spoken language models: A comprehensive survey”, is officially on arXiv. Check out this comprehensive survey -— it was a significant, collective effort and is packed with insights! |
| Jun 4, 2024 | “Learning Fine‑Grained Controllability on Speech Generation via Efficient Fine‑Tuning” is accepted to InterSpeech 2024! |